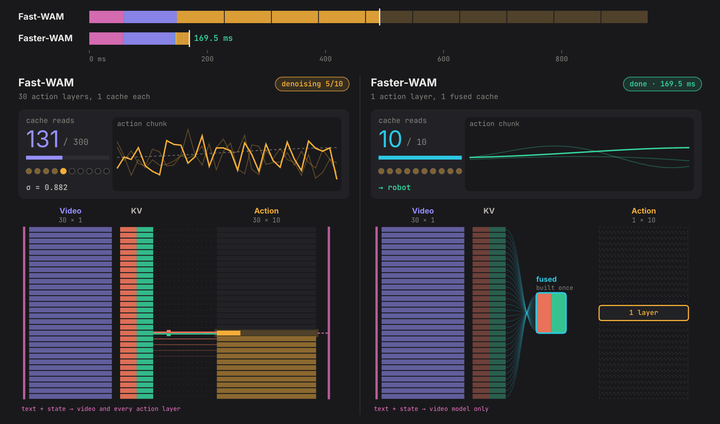
World action models vs VLAs: predict the video, or just the moves
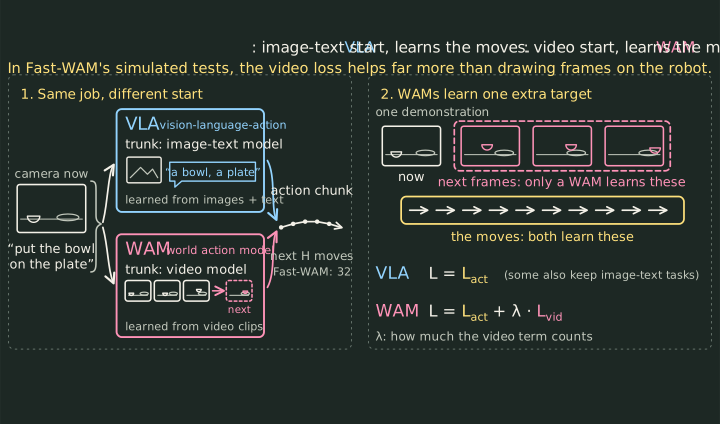
Both look at a camera image, read an instruction and output robot moves. A VLA starts from an image-and-text model and learns the moves. A WAM starts from a video model and also learns the frames that come next. Eight drawings on what that changes.
world-action-modelsvlaroboticsmachine-learning